Predicting touch from egocentric human video for contact-rich robot manipulation
1Carnegie Mellon University · 2Texas A&M University · 3University of Wisconsin–Madison · 4The University of Texas at Austin
†Corresponding author
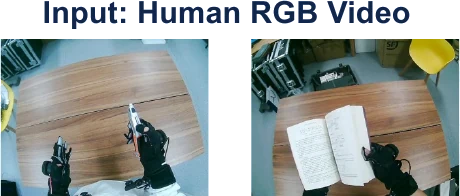
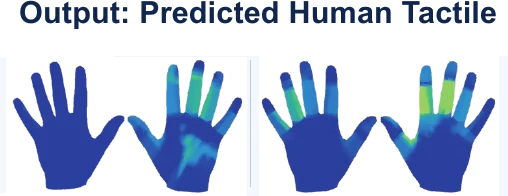
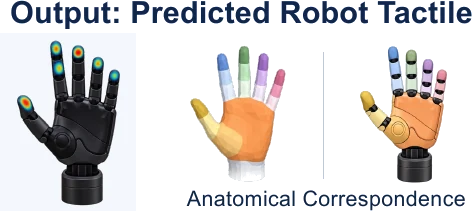
Contact locations and interaction forces are critical for contact-rich robot manipulation but are often ambiguous from vision alone. Measuring them on robots requires specialized tactile hardware and platform-specific data collection, which keeps robot tactile data scarce. Human egocentric video is far easier to scale but does not capture tactile information. Recent predictors trained on egocentric recordings paired with tactile-glove measurements can predict this missing signal from video alone. These predictors, however, remain confined to human hands, which differ from robot hands in appearance and tactile layout. We present Ego2Contact, which learns a visual–tactile prior from human interactions and transfers it to robot hands. Its predictor fuses temporal scene context with hand-local visual features to infer bimanual tactile fields from RGB video. Anatomical region correspondences align varying robot tactile layouts with the predictor's canonical grid, turning robot measurements into fine-tuning targets and predictions into policy inputs. Ego2Contact outperforms prior tactile predictors on human data, and on robot data after adaptation. The adapted predictor provides tactile inputs for both simulated reinforcement learning and real-robot policy post-training. Compared with training without tactile, predicted touch increases average success from 44.4% to 48.5% in simulation and from 27.5% to 45.0% on real robots, recovering part of the benefit of measured tactile. Human-learned tactile priors can thus supply touch when direct tactile sensing is limited.


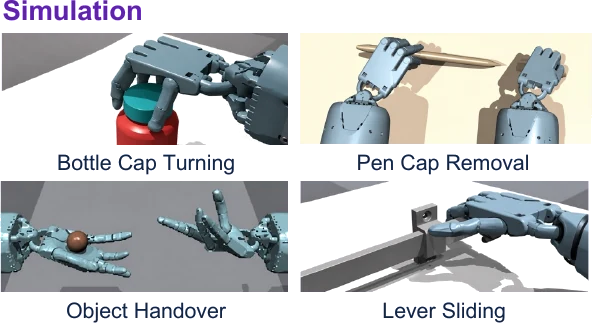
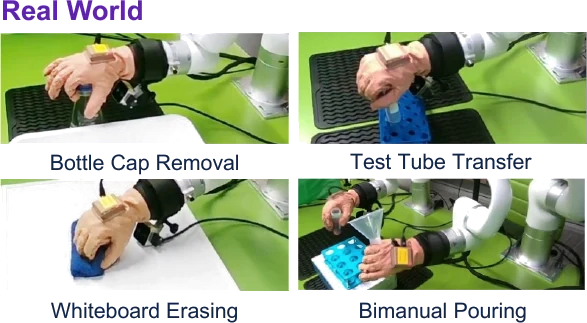
A visual–tactile predictor is learned from paired human egocentric video and tactile measurements, fine-tuned to a dexterous robot hand through anatomical region correspondences, and used to supply touch for policy learning across four simulated and four real-world contact-rich tasks.
Where contact occurs and how force evolves is not visible in a single image or hand pose.
Tactile sensors are hard to integrate and tied to one end-effector, so recordings rarely scale or transfer.
Glove datasets pair egocentric video with dense pressure, yet their predictors do not drive a robot policy.
Can a tactile prior learned from human video supply explicit touch observations that robot policies can consume?
Ego2Contact outperforms the TouchAnything baseline and a pose-conditioned variant on seen and unseen objects of EgoTouch. Each clip shows the RGB input (left) and the 21×21 pressure grids of both hands (right): ground truth on top, prediction below. Click a clip to enlarge it.
The predictor is fine-tuned on paired RGB and contact forces from simulated robot rollouts. Browse ground truth vs. prediction on held-out episodes: the 21×21 grid, the hand surface, and the 17 link regions the RL policy consumes.
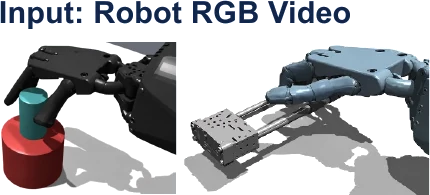
Four contact-rich dexterous tasks in Isaac Gym. PPO policies observe proprioception alone, or additionally online predicted or ground-truth tactile (17 pressure values and 17 contact flags per hand).
Successful executions of the four simulated tasks.
A dexterous hand wearing an 880-taxel tactile glove, with a head camera and a wrist camera. Demonstrations are collected by VR teleoperation, and the adapted predictor annotates them with tactile images for post-training a vision-language-action policy. Post-training uses no tactile, predicted tactile (ours) or measured tactile; every policy runs with measured tactile.
Average success rate over the four tasks
| Task | No tactile | Predicted | Measured |
|---|---|---|---|
| Bottle cap removal | 5/10 | 7/10 | 7/10 |
| Test tube transfer | 3/10 | 5/10 | 6/10 |
| Whiteboard erasing | 2/10 | 3/10 | 4/10 |
| Bimanual pouring | 1/10 | 3/10 | 5/10 |
Head-camera view with the wrist camera(s) inset at the top.
@article{yang2026ego2contact,
title = {Ego2Contact: Predicting Touch from Egocentric Human Video for Contact-Rich Robot Manipulation},
author = {Yang, Qianqian and Li, Dayou and Liu, Bangya and Zhu, Zihao and Chen, Nuo and Xu, Siyuan and Hu, Hezhen and Yu, Chen and Friesen, Rebecca and Zheng, Minghui and Hipwell, Cynthia and Qian, Xiaoning and Shimada, Kenji and Fan, Zhiwen},
journal = {arXiv preprint arXiv:2610.22932},
year = {2026}
}